In the darkroom. This engine is still being developed and tested; details can change.
WS-022 · FR 22 · Engine Room
Reel Edit Engine
Your clips, stills and voice in, a 9:16 reel with word captions in your own colours out.
A · Free · keyword REELCUT
The preset and the shotlist
The preset this engine reads and the shotlist template it fills. Enough to run one shoot by hand and see if it fits your brand.
Fig. 1 · The board
A Input slot
a folder of clips or stills + a read-aloud script (or a recorded voice)
B Engine
- 01video-edit
- 02captions
- 03voice-sound
- 04format-variants
- 05humanizer
route local · fallback gemini
C Contact sheet
shots.json timed on the words, final.mp4 in 9:16 (+ 4:5, 1:1) with word captions, title, end card, music
Data sheet
- Input
- a folder of clips or stills + a read-aloud script (or a recorded voice)
- Output
- shots.json timed on the words, final.mp4 in 9:16 (+ 4:5, 1:1) with word captions, title, end card, music
- Models
- elevenlabs
- Route
- local (fallback gemini)
- Command
- /make-reel
- Cost per run
- Local and free with the mock or macOS voice; a real voice-over costs ElevenLabs characters (about 15 words per 6 s)
- Maturity
- Working: used in production here
Fig. 2 · Sample output
3 frames · real output from this engine
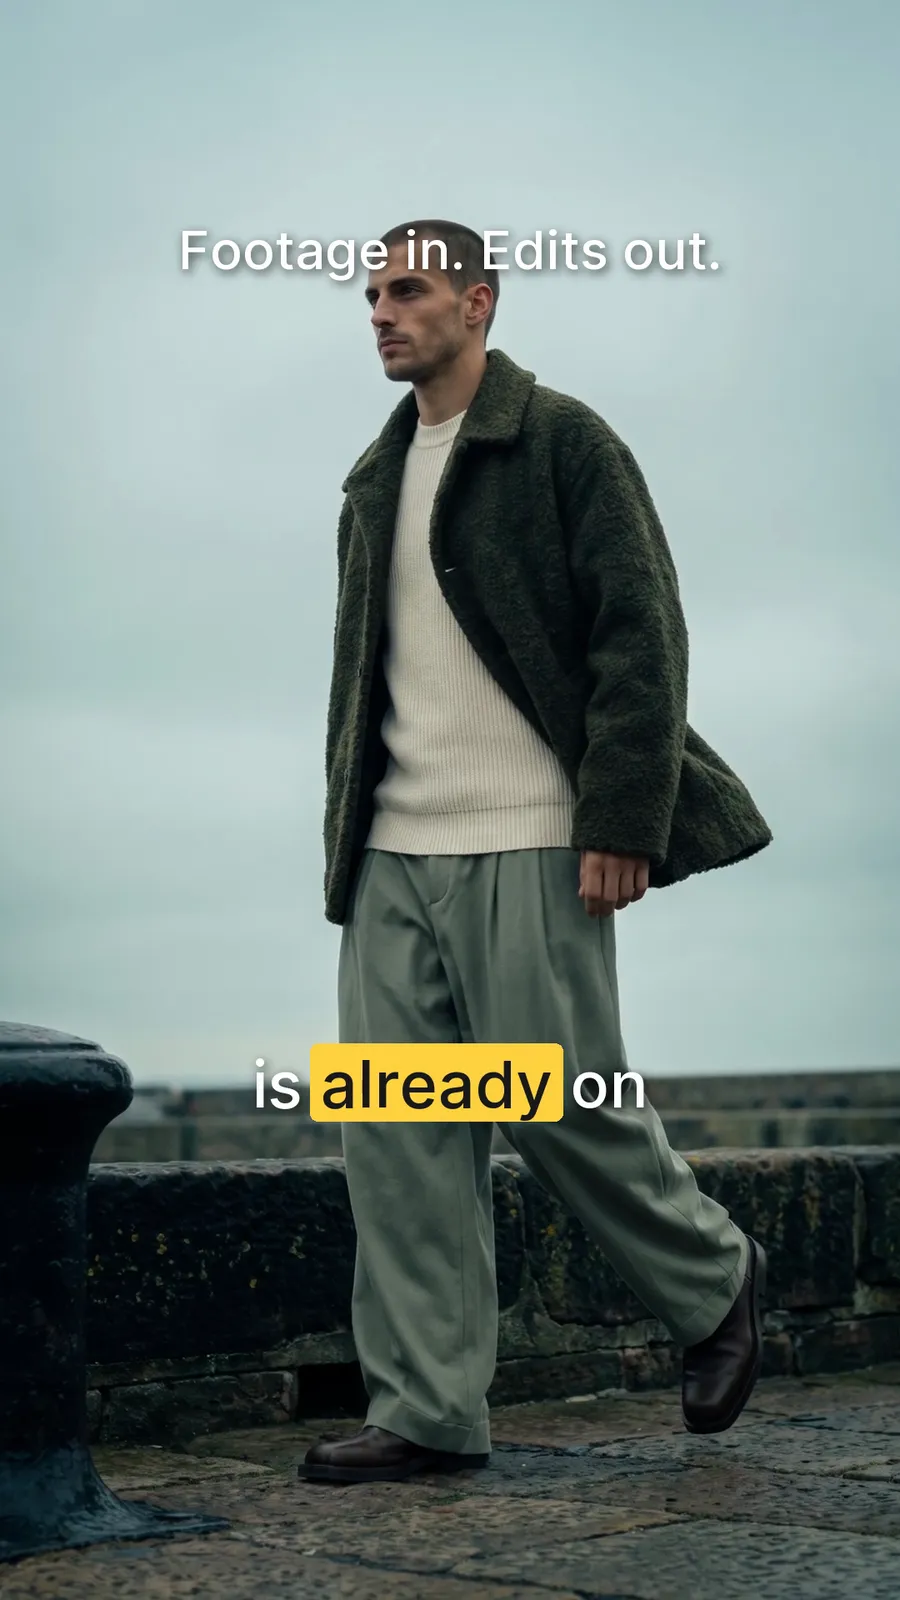
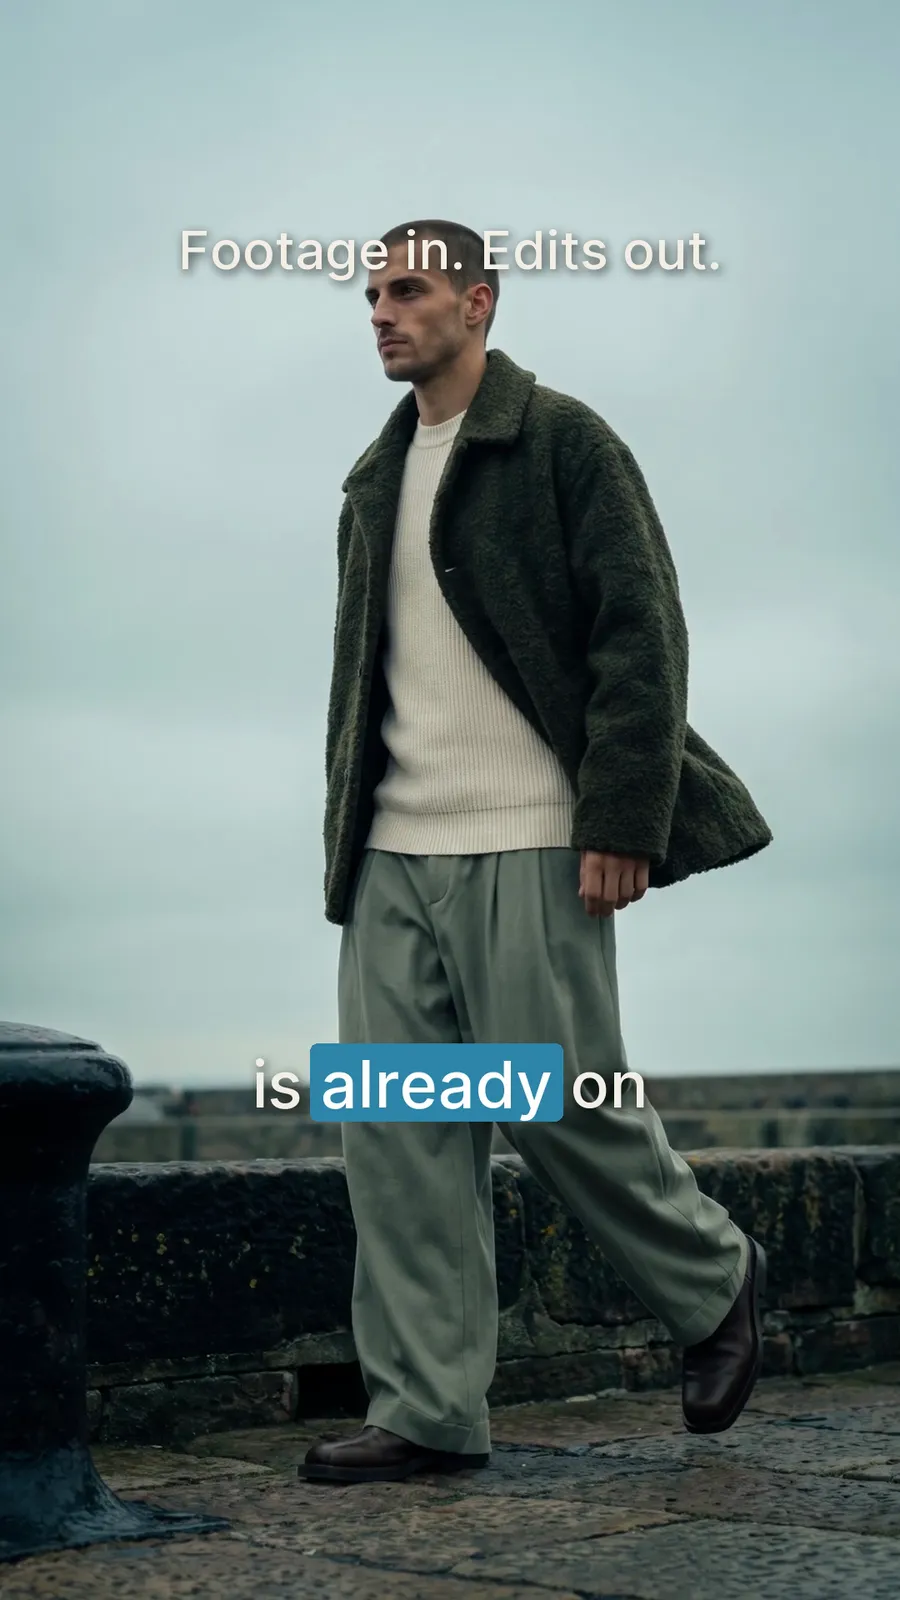
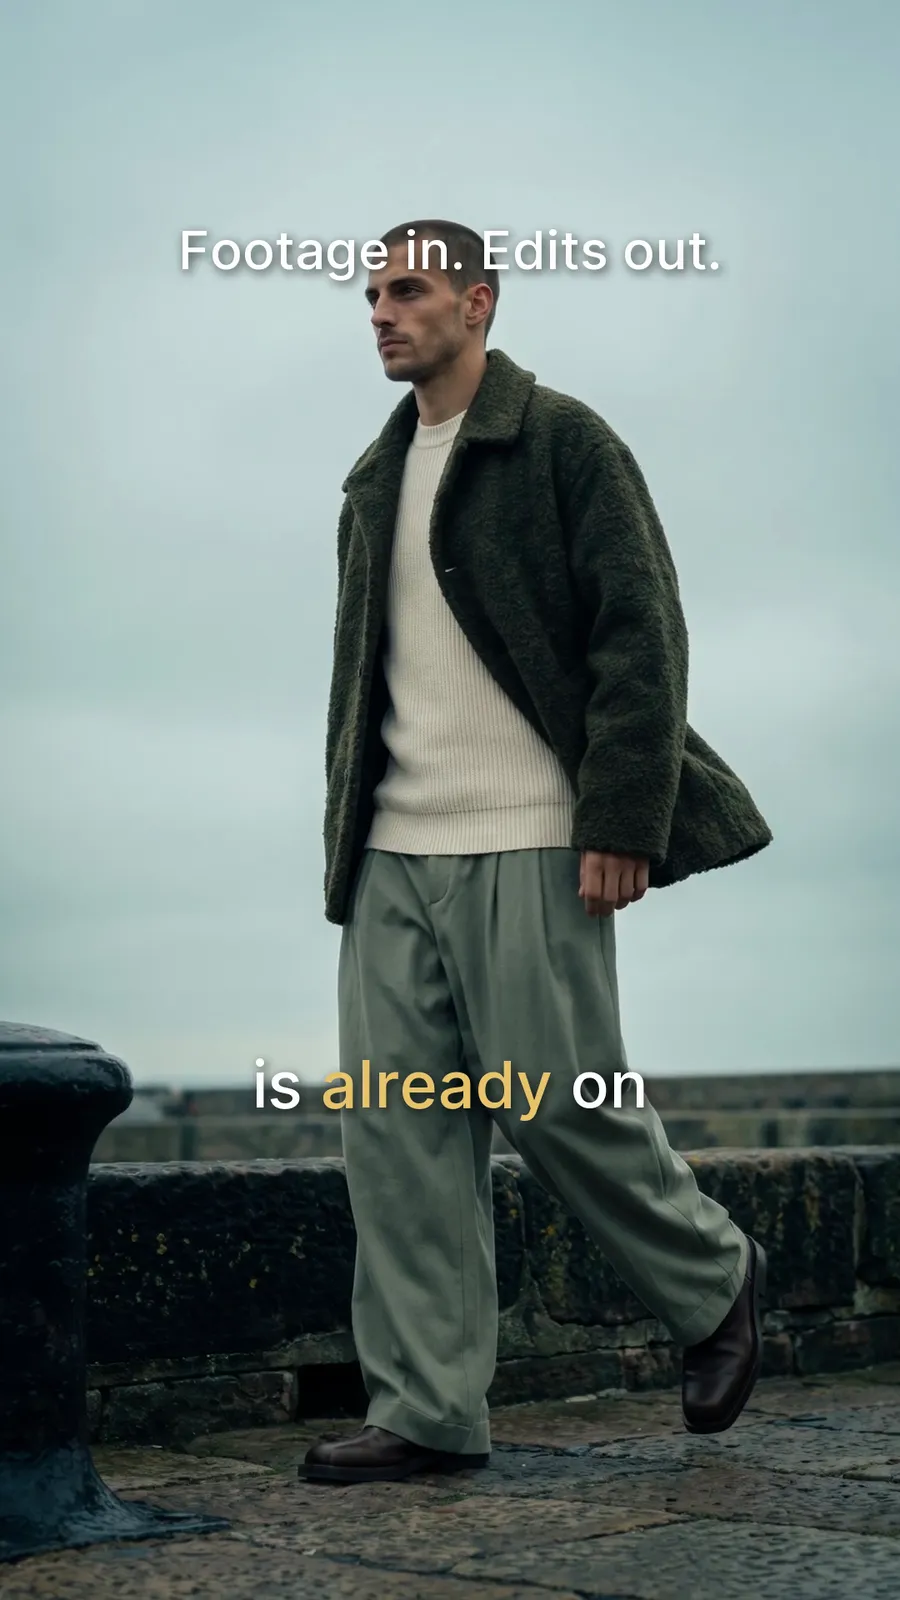
All images on this page are generated with this engine.
What it does
It cuts footage you already have on a voice-over: one shot change per beat, word captions in your brand colours, a
fixed title, an end card and music that ducks under the voice. Three caption styles (marker, calm, word-pop) all
read the brand’s tokens.json, so a new design system restyles every reel without touching the edit.
What you see in the post
The same reel twice, side by side: design system A with a yellow marker block, design system B with a blue one. Nothing else changed. Then the calm style on the same footage.
How it runs
/make-reel <folder> marker: the read-aloud script (delta hook, word budget,humanizer), approval of the text.core/voice/tts.py --mockfor free timings; a real ElevenLabs voice after the character count is approved.shots.json: a cut on a word, stills with push or pull, title, accent words,caption_style.core/video/assemble.py <render-dir>: render locally;format-variantsfor other ratios.- QC frames at every shot change: safe zones, sync, nothing over a face; approval of the picture.
What you get (the giveaway)
- free: the three edit styles with the token fields each one reads
(
../weadapt-studios-products/product/studios/video-edit-studio/free/) - studio: the Video Edit Studio for Claude Code and Codex
Honest limits
Mock-tested on our own film footage (2026-10-29): one reel in two token sets and in the calm style, mock voice. No real-voice run in the built studio yet. It cuts what you give it: a missing shot is named, never invented.